Traditional Chinese Bench
One image. One character. See how AI models read Traditional Chinese, from everyday characters to rare forms.
Model comparison
Select a model to inspect its answers.| Model | Strict | Recognition | Format |
|---|---|---|---|
| 95.3% | 95.3% | 100% | |
| 93.8% | 93.8% | 99.4% | |
| 93.8% | 93.8% | 100% | |
OpenRouter → DeepInfra | 92.7% | 92.7% | 100% |
| 89.1% | 89.1% | 100% | |
| 88.8% | 89.5% | 98.8% | |
| 87.5% | 87.5% | 99.8% | |
| 86.2% | 86.2% | 100% | |
OpenRouter → DeepInfra | 81.1% | 81.1% | 99.1% |
| 74.3% | 74.5% | 99.7% | |
OpenRouter → DeepInfra | 71.5% | 71.6% | 95.6% |
| 59.2% | 59.2% | 100% | |
OpenRouter → DeepInfra | 57.1% | 57.1% | 99.3% |
| 56.3% | 56.7% | 98.8% | |
| 50% | 50% | 95.4% | |
| 47.6% | 47.6% | 99.8% | |
OpenRouter → DeepInfra | 37.5% | 37.5% | 99.3% |
Strict requires the exact reply. Recognition accepts a clear final character despite extra formatting. Format measures the one-character rule. How scoring works
Scores by frequency band
Strict accuracy · 200 characters per band.
| Model | Very common | Common | Mid-frequency | Less common | Rare | Very rare |
|---|---|---|---|---|---|---|
| 100% | 99.5% | 96.5% | 95% | 92.5% | 88.5% | |
| 100% | 99.5% | 100% | 94.5% | 86% | 82.5% | |
| 99.5% | 99% | 98% | 89.5% | 90% | 86.5% | |
OpenRouter → DeepInfra | 97.5% | 99% | 97% | 93% | 89% | 80.5% |
| 99% | 98% | 96% | 87% | 77.5% | 77% | |
| 97% | 96.5% | 97% | 89% | 77% | 76% | |
| 98.5% | 98.5% | 99.5% | 96% | 70.5% | 62% | |
| 95.5% | 95.5% | 93.5% | 84.5% | 73.5% | 74.5% | |
OpenRouter → DeepInfra | 95% | 93.5% | 90% | 77.5% | 68% | 62.5% |
| 99% | 100% | 95.5% | 75% | 42% | 34.5% | |
OpenRouter → DeepInfra | 96% | 91.5% | 81.5% | 68% | 50% | 42% |
| 96.5% | 91.5% | 79% | 45% | 23.5% | 19.5% | |
OpenRouter → DeepInfra | 85.5% | 85% | 73.5% | 52% | 26.5% | 20% |
| 90.5% | 92.5% | 83% | 49.5% | 13.5% | 9% | |
| 94.5% | 87.5% | 67% | 34% | 12.5% | 4.5% | |
| 91% | 87.5% | 65% | 28% | 7% | 7% | |
OpenRouter → DeepInfra | 84.5% | 74.5% | 43.5% | 17% | 4% | 1.5% |
Inspect individual characters
Filter all 1,200 images, compare models, and open any image for the original replies. Results load when you open this section.
Exact counts & subset scores
Compare models & display options
No characters match these filters.
 ✓的Format issueExpected 的
 ✓是Format issueExpected 是
 ✓不Format issueExpected 不
 ✓我Format issueExpected 我
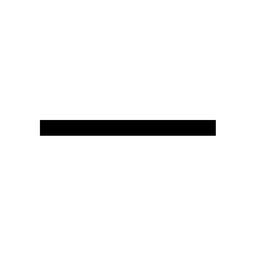 ✓一Format issueExpected 一
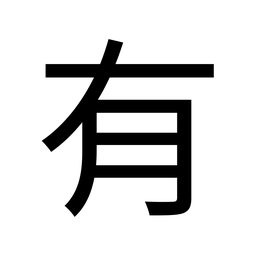 ✓有Format issueExpected 有
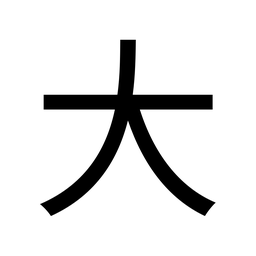 ✓大Format issueExpected 大
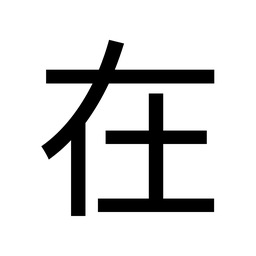 ✓在Format issueExpected 在
 ✓人Format issueExpected 人
 ✓了Format issueExpected 了
 ✓中Format issueExpected 中
 ✓到Format issueExpected 到
 ✓資Format issueExpected 資
 ✓要Format issueExpected 要
 ✓以Format issueExpected 以
 ✓可Format issueExpected 可
 ✓這Format issueExpected 這
 ✓個Format issueExpected 個
 ✓你Format issueExpected 你
 ✓會Format issueExpected 會
 ✓好Format issueExpected 好
 ✓為Format issueExpected 為
 ✓上Format issueExpected 上
 ✓來Format issueExpected 來
 ✓學Format issueExpected 學
 ✓就Format issueExpected 就
 ✓交Format issueExpected 交
 ✓也Format issueExpected 也
 ✓用Format issueExpected 用
 ✓能Format issueExpected 能
 ✓如Format issueExpected 如
 ✓時Format issueExpected 時
 ✓文Format issueExpected 文
 ✓說Format issueExpected 說
 ✓沒Format issueExpected 沒
 ✓他Format issueExpected 他
 ✓看Format issueExpected 看
 ✓那Format issueExpected 那
 ✓問Format issueExpected 問
 ✓生Format issueExpected 生
 ✓提Format issueExpected 提
 ✓下Format issueExpected 下
 ✓過Format issueExpected 過
 ✓請Format issueExpected 請
 ✓們Format issueExpected 們
 ✓天Format issueExpected 天
 ✓所Format issueExpected 所
 ✓多Format issueExpected 多
Method, scoring & audit records
All full-set scores use 1,200 images. Each frequency band uses 200 images. Values in the comparison table are percentages; exact counts are available on hover or keyboard focus. Frequency ranks use the historical 1993–1994 BIG5 source, not current usage ranks. Recognition is a post-hoc proxy, not a pure vision score. Missing or unclear answers remain in the denominator.
Prompt: Identify the single Traditional Chinese character in this image. Reply with only that one character. Do not add spaces, punctuation, explanations, or alternatives.
Each image was sent in a fresh request, without labels, character lists, or prior answers. The strict score requires the exact Unicode character after removal of surrounding whitespace. Different written forms and multi-character answers count as wrong under that rule.
Separate recognition score: the same deterministic extractor runs on every model's final response text. It does not receive the model name or expected character. It accepts a single Han character, a final single-character line, or a single character after an explicit ending statement, colon, arrow, equality, or English sentence. It can remove outer punctuation, Markdown decoration, invisible format controls, and variation selectors. It does not scan for the reference character, read hidden reasoning, normalize Unicode, or convert written forms. Lists and unclear endings are not given credit. The full 1,200-item denominator remains fixed. This is a post-hoc recognition proxy; it does not prove pure visual ability.
Separate format score: exactly one Han character after whitespace removal, whether that character is right or wrong. Original length-only format flags remain in the saved run files. A lone variation selector is a format failure here. Strict scores and raw replies are unchanged. Download the metric definitions, totals, format differences, and extractor source.
For Codex, the audit compared joined text chunks, done events, completed messages, saved answers, and scores. For Anthropic and OpenRouter, it checked the raw response JSON; Anthropic SDK-parsed text was also checked. It found no lost text or wrong message selection. Unicode checks are recorded in the audit files. Multi-character responses remain wrong under the agreed rule. For example, Luna returned 級籤 for 綎, and 幽屍 for 齶. These were model outputs, not parser errors.
Images are unchanged 256 × 256 RGB PNGs, using Noto Sans CJK TC Regular. This set gives each frequency band equal weight. It does not estimate accuracy on normal running text.
Download data and audit records
Original dataset (ZIP) — exact PNGs, frozen manifest, source ranks, full original font, and license.
Results and audits (ZIP) — every verified final reply, model settings, summaries, CSV exports, parsing audits, and scoring code.